Automatic Restart Policies for a Personal Agent
Four phases turn agent crashes into recoverable events.
A personal agent that runs unattended is only as good as what happens the moment it breaks. Most builders find this out the hard way: the demo works fine in a notebook, everyone claps, and then the thing goes into production and fails silently while nobody's watching. Getting an agent to run reliably unattended is a different engineering problem than getting it to run once, in front of you, on a machine you're staring at. This piece walks through what a real restart policy actually requires: detection, cleanup, state restoration, and backoff, in that order, and what changes when someone else hosts the thing for you.
Without a process manager sitting on top of it, a crashed agent just stops. No log entry explaining why. No saved state. No second attempt. Someone has to notice, SSH in, and restart it by hand, which is fine at 2pm and a disaster at 2am. A process manager turns that dead end into a recoverable event: it restarts the process, records what happened, and gives the agent a shot at picking up where it left off.
"Always-on" "Always-on" doesn't mean a process that never crashes. "Always-on" means a process that notices when it crashed, cleans up after itself, restores enough state to make sense of where it was, and gets back to work, all without a human doing the noticing or the restarting. It means a process that notices when it crashed, cleans up after itself, restores enough state to make sense of where it was, and gets back to work, all without a human doing the noticing or the restarting. That's the whole game, and it breaks into four layers.
The four crash-recovery phases every restart policy must cover
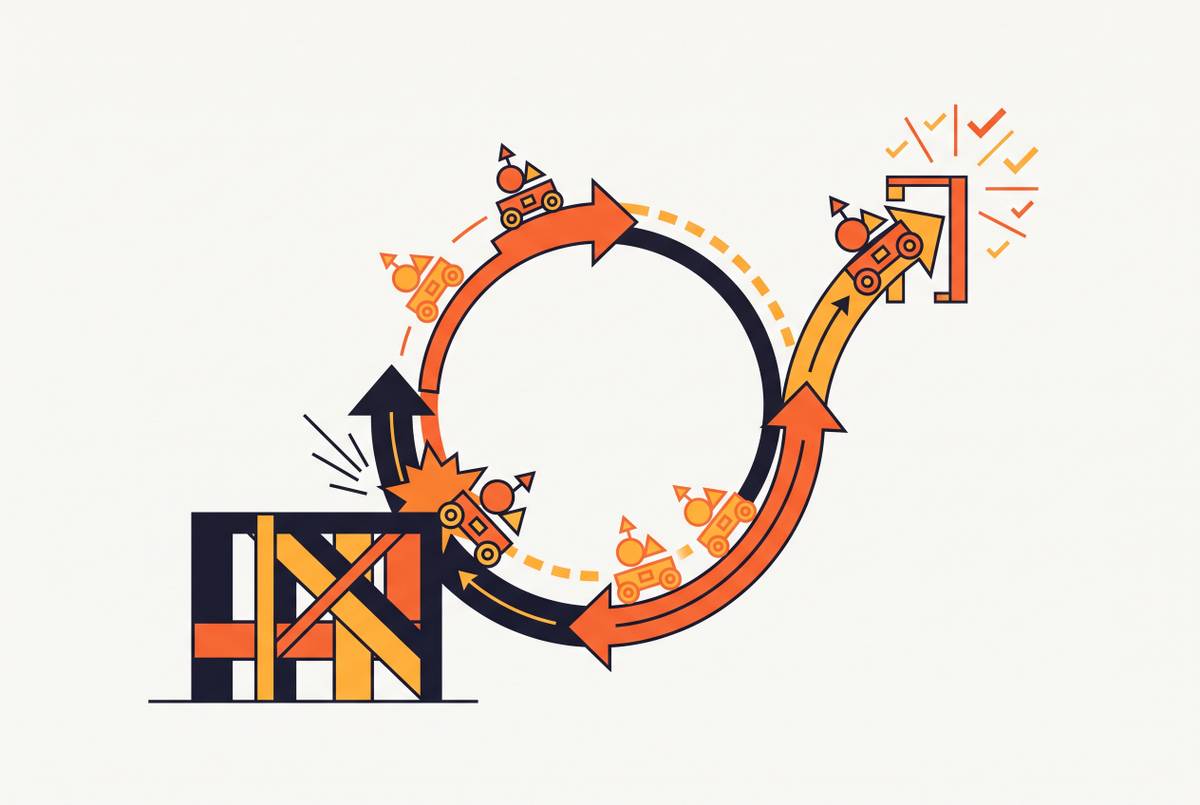
Every crash recovery, regardless of framework, regardless of who's hosting it, moves through the same four phases: detection, cleanup, state restoration, restart. The order isn't a style choice. Skip cleanup and go straight to restoration, and you risk rebuilding state from files that a half-finished write already corrupted. Skip detection entirely, and cleanup never fires in the first place, because nothing told the system there was anything to clean up.
Done right, these four phases turn a crash from a catastrophic event into a minor blip, the kind measured in seconds, not the kind that eats an afternoon of debugging and an apology email to a customer.
Each phase breaks in a specific way when it's missing:
- No detection: the process hangs, looks alive to anyone checking on it, and does nothing. Silent failure is worse than loud failure, because nobody knows to intervene.
Cleanup fails too: file handles stay open, database connections stay locked, and partial writes sit there corrupting whatever tries to read them next.
- No state restoration: the agent starts over from zero every time, forgetting whatever task it was three steps into.
- No backoff: the restart loop slams a struggling dependency over and over, and turns a minor outage into a real one.
Each of the next four sections takes one of these apart.
Detection: how a policy knows the agent has failed
Detection has three distinct mechanisms, and they catch different failure modes. None of them alone covers the whole picture.
Process exit monitoring catches the clean case, where the process dies, the operating system reports it, and the process manager knows immediately. No false negatives here. If the process is gone, this catches it, instantly.
Health check polling catches the messier case: a process that's technically still running but not doing anything useful. It's alive, in the sense that the OS still sees it, but it's stuck, or deadlocked, or spinning on a bad response it never got. The polling interval is a tradeoff: check too often and you burn cycles on overhead, check too rarely and a stuck agent sits broken for minutes before anyone notices.
Timeout watchdogs catch stalls, specifically. A process that isn't crashed, isn't hung exactly, but has just stopped making progress toward whatever it was doing. Neither of the first two mechanisms flags this on its own.
There's a fourth wrinkle that isn't really a detection mechanism so much as a detection trap: the unknown state. An agent fires off an action, say, a payment call or a message send, and the response never comes back. Did it succeed and the response got dropped somewhere on the wire? Or did it never fire at all? Treating silence as failure and retrying blind is how duplicate charges and duplicate messages happen. The agent needs to reconcile, actually check what happened, before it decides whether to retry.
One practical trap for agent owners specifically: health check intervals and watchdog timeouts get tuned around simple queries, and then a genuinely hard multi-step reasoning task takes four times as long as expected and trips a false positive. The timeout has to account for how long the agent is realistically allowed to think, not how long a toy example takes.
Kubernetes users will recognize the liveness-versus-readiness split here. Liveness tells the orchestrator to restart the thing or not. Readiness tells it whether to send traffic to it. For an agent that's exposed to outside callers, both matter, and they answer different questions.
Cleanup: what has to happen between a crash and a restart
Cleanup is the unglamorous middle step, and people skip it because it doesn't appear in a demo. Three things need handling before a restart makes sense.
Locked resources have to get released: file handles, open database connections, API sessions that the crashed process never closed. Incomplete writes need to get flushed or thrown out entirely, because a half-written checkpoint is worse than no checkpoint at all; it looks valid until the restoration phase tries to load it and everything downstream goes sideways. And any tool call that was in flight when the crash hit needs to get cancelled and logged, not silently retried, because nobody knows yet whether that call actually landed on the other end.
That last point rests on a design choice that has to happen before the crash, not after: idempotency. If an action can't be safely repeated, that needs to be known and flagged at the tool-call level from the start. Cleanup works most cleanly when idempotency has been designed in from the start, so the system can distinguish actions that are safe to repeat from those that aren't.
Cleanup is also, conveniently, the right moment to write a structured failure event: timestamp, last known state, what was mid-flight when things went dark. That record needs to exist before the process image disappears, because once it's gone, so is the evidence.
There's a governance dimension here too. Enforcement for what an agent is and isn't allowed to do needs to happen outside the model itself, at the point where actions actually execute, not inside the LLM's reasoning. Cleanup is exactly that enforcement boundary: unconfirmed, in-flight actions need a policy decision, not another round of the model guessing what it probably did.
State restoration: checkpoint strategies that let an agent resume rather than restart
Once cleanup's done, the agent needs to figure out where it was. Two strategies dominate here, and they trade off speed against fidelity.
Full event replay stores every tool call, every model response, every state change, and rebuilds the agent's state by replaying the whole log from the start. It's exact, in theory. In practice it's slow for anything long-running, and it assumes every operation is deterministic, which tool calls often aren't. Replay the same API call twice and you might get a different answer the second time.
Incremental reconstruction is the more common middle ground: load the last checkpoint, then replay only what happened after it. Faster than full replay, more accurate than a raw checkpoint alone, and it's what most production agents actually use.
Checkpointing has matured as a pattern: save state through a checkpoint mechanism backed by a relational database or Redis, and wire that saved checkpoint into a trace as a span attribute. That combination gives a full decision history and the ability to replay any past state during an incident, which matters a lot more than it sounds like at 2am when something's broken and nobody knows why yet.
Where the checkpoint actually lives changes how fast recovery happens:
- In-memory storage is fastest, but it's gone the instant the process dies. Fine for context inside a single step, useless for surviving a crash.
- Redis is fast, supports automatic expiration, and works well for session-level state in agents that need to remember things across a conversation.
- Postgres, or something equivalent, is slower but durable. It's the right home for checkpoints that need to survive not just a process crash but a host going down entirely.
Memory allocation sizing affects whether the agent process can even start: Memory sizing for the restart path deserves its own attention, since startup demands can differ meaningfully from steady-state operation. Sizing memory for steady-state operation and ignoring the restart spike is a common way to watch a recovery attempt fail for reasons that have nothing to do with the agent's logic.
Hermes adds a wrinkle: its closed learning loop writes Markdown skill files after tasks that involve a meaningful number of tool calls, typically five or more. Its closed learning loop writes Markdown skill files after tasks that involve a meaningful number of tool calls, typically five or more. Those files are persistent state, every bit as real as conversation history, and if the checkpoint strategy doesn't account for them, a crash wipes out accumulated performance gains, not just the current task. Skill refinement in Hermes measurably speeds up execution after enough repeated similar tasks; losing that state means starting the learning curve over.
Backoff and retry: bounding how aggressively a policy tries to recover
Restarting immediately, every time, in a tight loop, sounds like the safe default. If the thing that crashed the agent was a degraded dependency, an API that's timing out or a rate limit that's already been hit, restarting immediately, every time, in a tight loop, is not the safe default it sounds like: hammering it with instant restarts just makes the outage worse and can... If the thing that crashed the agent was a degraded dependency, an API that's timing out or a rate limit that's already been hit, hammering it with instant restarts just makes the outage worse and can burn through the rate limit budget for everyone else hitting that same API.
Exponential backoff with jitter is the standard fix: each retry waits longer than the last one, and a random jitter gets added so that if several agent instances crash at the same moment, they don't all retry in lockstep and slam the dependency at the exact same second.
Retry budgets cap how far this can go, either in total retry count or in calendar time, before the policy gives up and escalates instead of looping forever. For an agent running overnight with nobody watching, this is a requirement. It's the difference between a failed task sitting quietly in a queue and a runaway loop burning through API credits until someone wakes up.
Circuit breakers add a third layer: after enough consecutive failures, stop retrying entirely and just hold. If the dependency, a model endpoint, an external API, whatever it is, is genuinely down, retrying doesn't help anyone. It just adds noise.
The strongest retry setups combine all of this with idempotency guarantees and a clear path to a human when the stakes are high enough. Anything touching money, legal exposure, or customer records needs an escalation path to a person, not just another retry attempt.
None of this is worth much if it's untested. Fault testing beats happy-path testing here: simulate slow responses, duplicate webhooks, expired tokens, 429s, malformed payloads, and the nastiest case of all, a provider that completes the request successfully and then just drops the response on the way back. That last scenario is the same unknown-state problem described in the detection section, occurring again at the retry layer.
Process managers that operationalize these policies for agent runtimes
All four phases above are policy. Something still has to run them.
Botctl is a lightweight process manager built specifically for autonomous agents: daemon lifecycle, restart policies, log aggregation, health-check-driven restarts, pidfiles, restart counters, and structured output that plugs into systemd or supervisor. It's the right tool when an agent is running as a long-lived Unix service and someone wants that service managed the way any other daemon gets managed.
Container orchestration, ECS or Kubernetes, solves a related but bigger problem: persistent compute, load balancing, and automatic restarts for stateful agents, with readiness and liveness probes configured so the orchestrator actually knows when an instance is healthy versus just running. Kubernetes' Agent Sandbox controller goes further, adding deep hibernation that saves state to persistent storage, automatic resume when a network connection reappears, a stable hostname across restarts, and full pause and resume lifecycle management.
A warm pool of pre-provisioned sandboxes cuts the time it takes to spin up a fresh instance, which matters when restart latency is something end users will actually notice, not just something logged in a dashboard nobody checks.
None of this means anything without observability. Structured logging that captures the reasoning trace, the tool calls, and the decisions made along the way is the only thing that makes a 2am crash debuggable the next morning instead of a mystery. Emerging semantic conventions for tracing AI agents (still experimental as of early 2026) describe a hierarchy: a parent task span, child step spans underneath it, and individual model-call and tool-call spans nested inside those. That structure is what lets someone ask a question like "show every task where a step took longer than 30 seconds" and actually get an answer.
Multi-agent frameworks add their own layer here. CrewAI, for instance, added task callbacks, hierarchical process support, and parallel task execution, with built-in tracing that routes spans to its own platform via OpenTelemetry, though getting those same spans into something like Grafana Tempo still takes manual exporter configuration. In a multi-agent setup, one agent's restart doesn't stay contained. In a multi-agent setup, one agent's restart ripples outward and doesn't stay contained.
A separate reliability agent watches the primary agent's trace spans, catches a failure mode as it develops, and dispatches a remediation sub-agent with a narrow, constrained toolset to fix it. The remediation workflow needs its own trace, causally linked back to whatever span triggered it, or the whole thing becomes just as hard to debug as the original failure.
How OpenClaw and Hermes each present distinct restart-policy challenges
OpenClaw runs on Node.js, with Node 26 now the recommended baseline and Node 24 LTS (24.16 and above) as the floor. That matters for restart policy because Node's process management tools, the cluster module, PM2, systemd units, behave differently across versions, and a restart script tuned for one Node release can misbehave on another.
The bigger issue with OpenClaw is security, and it changes what a restart policy actually needs to do on resume. Independent trackers logged 137 security advisories, including five formal CVEs, across a three-month stretch in early 2026, among them a remote-code-execution flaw rated 8.8 on the CVSS scale. Separately, tens of thousands of exposed OpenClaw instances have turned up on the public internet, many with no authentication configured and sandboxing left off by default. Against that backdrop, an instance that crashes and auto-restarts back into an unauthenticated, unsandboxed state is a worse outcome than the original crash. A restart policy for OpenClaw needs a security check baked into the resume step: confirm authentication is live, confirm sandboxing is actually configured, before the instance takes a single connection. The project's large community, reflected in a very high count of GitHub stars, means restart recipes and tooling are easy to find, but it also means exposed instances are a live target, not a theoretical one.
Hermes runs on Python, 3.11 or newer, and its restart-policy challenge is different in character. Its closed learning loop, the same skill-file mechanism described earlier, means Hermes carries more persistent state than a plain stateless agent, and any checkpoint strategy for it has to cover the skill index alongside conversation history, not instead of it. Hermes launched in February 2026 and has already drawn over 22,000 GitHub stars and a solid number of contributors, which is a fast start, but it also means production hardening patterns for it are still being worked out in public rather than settled. Hermes also ships with built-in cron support, letting the agent trigger its own recurring tasks. That raises a specific question a restart policy has to answer: if a cron-triggered run gets interrupted mid-execution, does the next scheduled run go ahead anyway, or does it wait for the interrupted run to get reconciled first? Getting that wrong means either duplicate work or a scheduled task quietly skipped.
What managed hosting changes about restart policy ownership
Self-hosting all of this costs more than server bills. It costs time: VPS setup, Docker configuration, SSH access management, process manager configuration, health check wiring, checkpoint storage provisioning, and then being the person who gets paged when a restart loop fails at 2am. That's a real, recurring tax on whoever's running the thing.
A managed platform absorbs a good chunk of that tax directly. Detection becomes the platform's job: it watches the sandbox, not the operator watching a dashboard. Restart mechanics happen automatically, without anyone hand-configuring a process manager. State persistence gets handled by default too: whatever's in the home folder survives restarts without anyone building custom checkpoint logic to make that happen. Idle management comes along as well, with sandboxes sleeping after a period of inactivity, by default around 300 seconds, and waking back up on the next request, a lifecycle that's managed rather than configured by hand.
What doesn't disappear is the stuff that's genuinely a judgment call, not a mechanical one. Spend caps, set at instance creation, bound how much a runaway agent can cost before something stops it, functioning as a policy-layer version of a retry budget. Cron schedules are still something the operator sets, though the platform runs and logs the results. And integration auth, OAuth connections managed across more than a thousand toolkits as of August 2026, still gets configured by whoever's setting up the agent, even though the platform's credential lifecycle system handles token refresh automatically.
Managed hosting doesn't eliminate restart policy. It relocates ownership of the mechanical parts, detection, restart execution, state persistence, so the operator's left holding the parts that actually require a decision: how much this thing is allowed to spend, when it's allowed to run, and what it's allowed to touch.