What Ground-Up Agentic Infrastructure Means for a Founder Who Just Wants Their Agent to Run
November 3, 20268 min read1,808 words
Text: Marcus Oyelaran
Building agents that run in production requires infrastructure far beyond a working model.
Managed cloud hosting for AI agents should take responsibility for isolated execution, persistent state, tool connections, monitoring, and recovery (not just rent out compute). For a founder, “ground-up agentic infrastructure” means the whole system needed to keep an agent running for every customer. The practical choice is to own the parts that distinguish the product and outsource operations unless control requirements or proven economics justify taking them on.
Why the demo-to-production crossing is harder than it looks
A real user hits the endpoint and waits four seconds. The second triggers a race condition. The third bypasses the guardrails. These are the failures a controlled demo can hide, because a successful interaction says little about how the system behaves under simultaneous, unpredictable, or adversarial use. These failures expose the structural gap between a working interaction and a working product.
Blaxel’s deployment guide identifies five categories of failure that prototypes conceal, including latency compounding, security assumption collapse, state management gaps, token cost variance, and unforgiving reliability math. Latency can trigger retries, which increase token costs and strain reliability budgets. A fix aimed at one symptom can therefore put pressure on another part of the system. Getting an agent to run in a notebook is a solved problem, but keeping it running continuously means engineering the dependencies around it.
What a production agent actually consists of, beyond the model
Storage holds temporary conversation history, persistent memory, tool-call history, and evaluation data, with vector databases supporting semantic memory. Each kind of state needs provisioning, backup, and expiration rules. Communication connects REST APIs, WebSockets for streaming, message queues for asynchronous work, and gateways for authentication and rate limiting. Every external tool adds credential management, error handling, and retries to that layer.
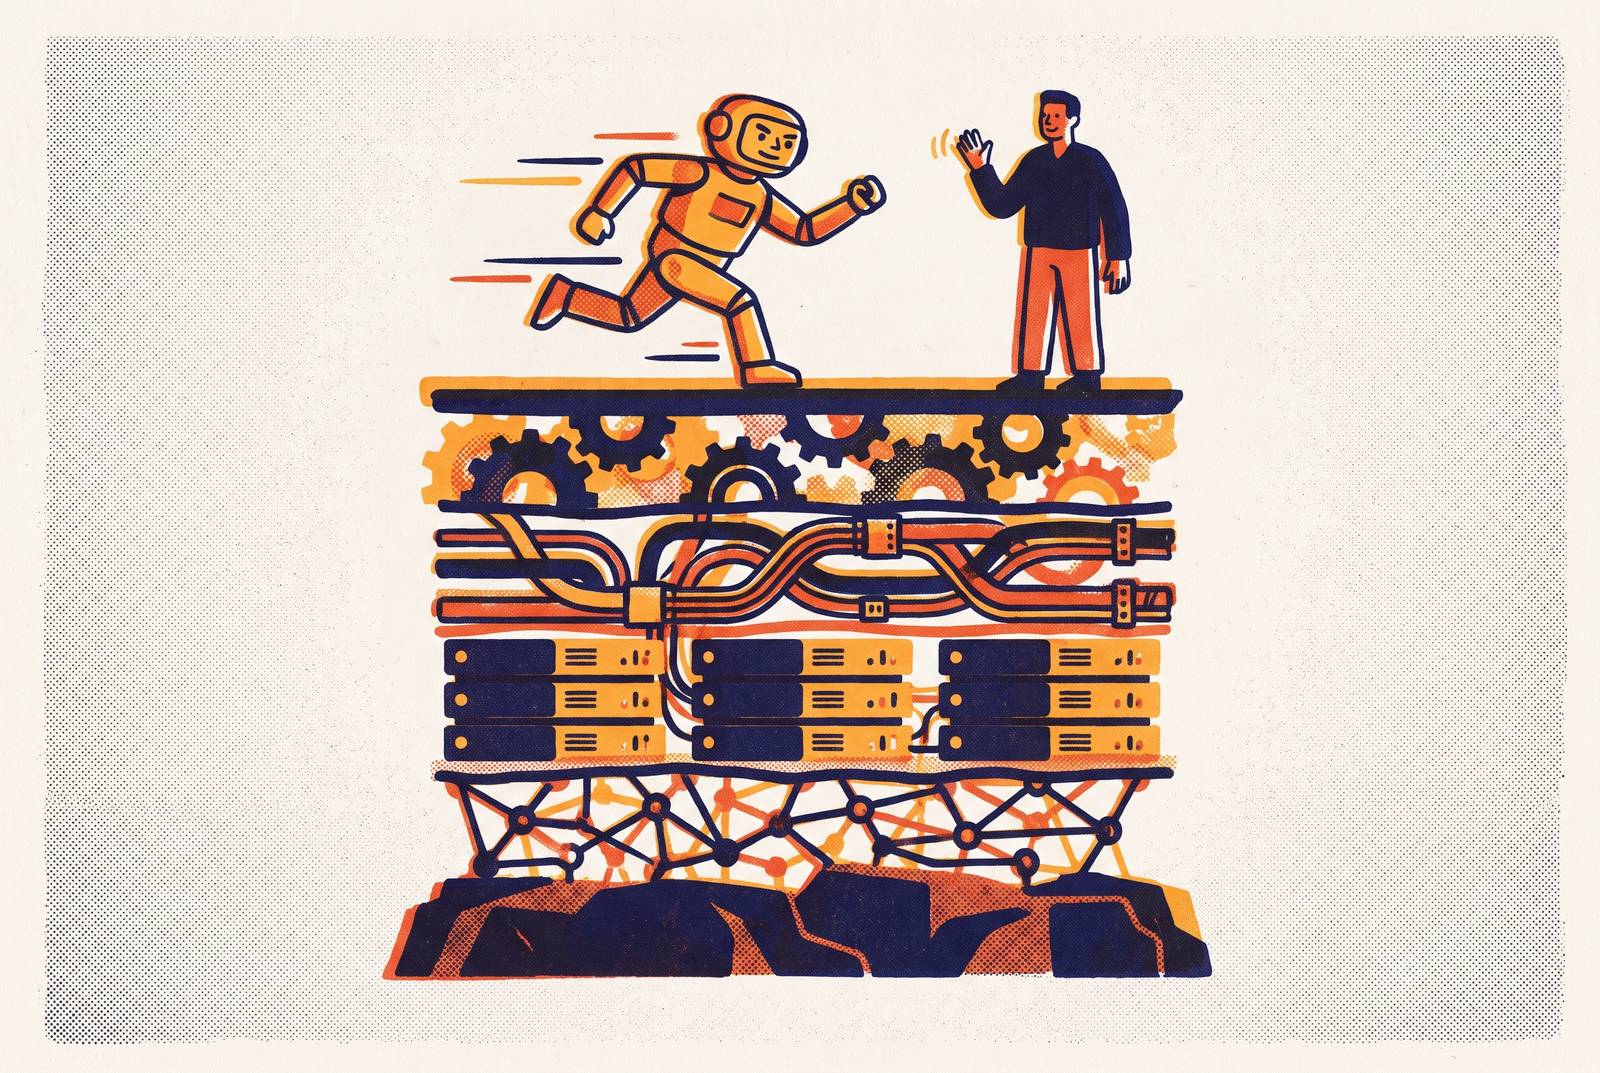
Observability explains what happened inside an agent’s work. Standard application performance monitoring can report request latency without showing the tool calls, model calls, retries, handoffs, and finish reasons that explain the result. Security governs access through key vaults, network policies, and scoped credentials rather than treating environment variables as a safe home for secrets. Execution and orchestration determine how capabilities run and work together. Each layer has its own job and adds work that a model API does not do.
MLflow’s 2026 production guide favors discrete, independently deployable capabilities over a monolithic agent that becomes brittle in production. That separation allows a sub-agent to be replaced as models evolve without making every capability part of the same change. The lesson for a team building this stack is to adopt open communication standards before inventing custom ones. MCP handles the exchange of tool-context, while A2A lets agents communicate with each other. Retrofitting those boundaries later is painful, because the communication design is already woven into the product.
Where most agent architectures break under multi-tenant load
Running one agent for its creator and running an isolated agent for every customer are different architectural problems. More compute does not resolve that difference. A multi-tenant service must keep each customer’s data and execution environment separate even when an agent runs unsafe code or a session is compromised. Treating this as a throughput problem misses the security boundary that the product now needs. Both how much work can run and how far a failure can spread matter.
Blaxel’s guide distinguishes namespace-level container separation from microVM isolation for AI-generated code and multi-tenant workloads. Firecracker, for example, provides a separate kernel per workload, containing similar exploits more effectively than shared-kernel Docker/runc environments. That distinction addresses the danger that one compromised tenant session can affect other tenants’ data and execution environments. OWASP’s Agentic AI category ASI08 names this pattern Cascading Failures, where a single fault propagates across agents and compounds into system-wide harm.
MLflow’s guide places most runtime risks at the skill and plugin execution layer. The guide therefore calls for deterministic enforcement beneath the model to block unsafe actions before they reach the wire. A prompt is not an enforcement boundary. The OWASP Top 10 for Agentic Applications, the related Agentic Skills Top 10, and NIST AI RMF provide the governance frame, while EU AI Act Article 14 sets human oversight requirements for high-risk systems. Designing those controls after an incident, compliance finding, or board intervention turns an architectural responsibility into an expensive repair.
The integration layer: why connecting agents to real tools is where agent products stall
An agent can answer a question and still fail to carry out a task. Access to Gmail, Slack, GitHub, or Salesforce depends on OAuth flows, token refresh, rate limits, retries, and APIs that change. That work does not end at launch. The communication layer is an active operating commitment, because the product depends on tools outside its control. For many agent products, this becomes the constraint before either model capability or compute.
Composio’s August 2026 catalogue lists over a thousand toolkits exposing more than 20,000 individual tools through a single MCP endpoint. Its platform handles OAuth flows, token refresh, rate limits, retries, and API drift, presenting structured tools that agents can call directly. Composio is SOC 2 Type II attested and ISO 27001:2022 certified. Those credentials do not show whether the service will stay up.
Composio’s own April 2026 status record showed API degradation that built up over time and roughly 36-hour downtime for webhook triggers for several apps. A cleanup job had stopped pruning a trigger-processing table. With a managed service, the provider has to do that repair work, though an outage can still affect the product customers use. The product remains dependent on the plumbing whoever maintains it.
What coding agents like Claude Code and Codex actually require to run in production
Claude Code and Codex make it easier to use what the agent can do, but teams still have to decide how to host it. The execution environment still needs an owner. Filesystems, processes, networks, credentials, and customer data remain security concerns even when a major lab manages the model. The important distinction is between managing the agent’s reasoning and managing the environment in which its tools act. A product can outsource one while retaining responsibility for the other.
Anthropic shipped self-hosted sandboxes for Claude Managed Agents to public beta in May 2026. In that arrangement, orchestration stays with Anthropic while tool execution runs on infrastructure controlled by the operator, including the agent’s filesystem, processes, and network. This lets agents work with data that must stay on the operator’s network. Managed orchestration therefore does not remove the need to run and secure the sandbox. Anthropic’s guidance makes the credential boundary explicit by warning operators never to set the main Anthropic API key on the worker host, because agent tool calls could read it.
OpenAI’s Codex spans a cloud agent for long tasks in an isolated, managed sandbox, a local CLI, a ChatGPT desktop app, and an IDE extension. The cloud sandbox provides a managed environment for its tasks, while the local surfaces put execution in a different setting. For a founder choosing among them, the lesson is to evaluate where work runs and who controls it rather than treating the agent’s name as an infrastructure specification. Model capability alone does not answer whether a customer’s work is isolated, how state persists, or who responds when execution fails.
How should a founder choose managed cloud hosting for AI agents?
The decision starts with total ownership cost. A VPS price leaves out setup, monthly operations labor, incident response, and security maintenance. Those costs still consume engineering time even when they have no separate line on an invoice. Running a full self-hosted LLM stack adds a meaningful fraction of an infrastructure engineer’s labor and substantial monthly compute. For a founder, that is time taken from improving the product or finding customers.
Volume changes the calculation, but staffing changes it too. At lower volumes, managed platforms almost always cost less when the bill includes all the engineering time. At higher volumes, self-hosting can cost less when DevOps staff are already on the payroll. Hiring that capacity solely to save on hosting reverses the supposed saving.
The recommendation therefore depends on the workload. For an early-stage customer-facing agent, managed hosting is the default when it takes on the runtime, isolation, persistence, monitoring, and recovery work. For products that connect to many tools, a service such as Composio handles the tool-connection layer, leaving the rest of the hosting stack to other services. For long coding tasks, Codex’s cloud agent has an isolated, managed sandbox, while Claude Managed Agents with self-hosted sandboxes lets operators keep tool execution on infrastructure they control. These options solve different portions of the problem, so none earns a blanket “best” label from model capability alone.
Sovereignty and long-run economics are serious objections to outsourcing. Data restrictions can require operator-controlled execution, and very high token volumes can favor self-hosting on reserved GPU infrastructure. Most early-stage agent products are nowhere near that volume, however, and spending months building for it buys an optimization before the business needs it. Teams should decide which layers to own one by one, based on the control they need or proven savings that make the work worthwhile. That permits managed orchestration and owned execution to coexist when the workload calls for it.
Stripe let software companies accept payments without becoming payments companies. Agent infrastructure poses the same business choice. A founder selling an agent does not automatically need to become an expert in provisioning, monitoring, and recovering a separate instance for every customer. Purpose-built managed hosting should be judged by how much of that responsibility it actually assumes. A cloud wrapper that leaves those jobs with the founder has not resolved the central operating problem.
The correct unit of scale for an agent-powered business, and what it implies for onboarding
The architectural unit that follows from these requirements is one isolated, persistent agent per customer. Persistence gives the customer an ongoing agent. Isolation establishes a boundary around that customer’s data and execution. That boundary addresses the cross-tenant leakage and cascading failures that shared execution makes difficult to contain. It must be enforced by the infrastructure.
Provisioning belongs in onboarding. The implementation should activate the customer’s instance automatically through an API, with no manual setup step. Hand-provisioning every new agent makes customer growth depend on repeated founder labor. It also leaves a central part of delivering the product outside the product itself.
For operators and SaaS companies, white-label infrastructure extends that design to a private, persistent, branded agent for each customer. The operator sells what the agent can do under its own brand, with managed infrastructure running underneath. Branding changes what the customer sees while preserving the isolation requirement, and automatic provisioning removes the need for the founder to configure each deployment. When both provisioning and operations are handled that way, acquiring another customer no longer creates another hand-built infrastructure project. The founder’s time can go to the two activities that compound, improving the agent and acquiring customers.